Ransomware groups no longer just encrypt your files — they hunt for your backups first. If your backup strategy hasn’t evolved in the last few years, it’s probably one misconfigured share away from being useless on the day you need it most.
The 3-2-1 backup rule is not new or flashy. It’s a decades-old discipline from the photography and IT disaster recovery world, repurposed into one of the few genuinely reliable defenses against ransomware. Unlike firewalls, EDR, or awareness training, backups are the control that determines whether a ransomware incident is a bad afternoon or a company-ending event.
This article breaks down what the 3-2-1 rule actually means, why attackers specifically target backups now, how to implement it step by step, and where the rule needs an upgrade to survive modern ransomware tactics.
What the 3-2-1 Backup Rule Actually Means
The rule is simple to state and hard to execute well:
- 3 copies of your data — the original plus at least two backups
- 2 different storage media or types — e.g., local disk/NAS and cloud object storage
- 1 copy stored off-site — physically or logically separate from your primary environment
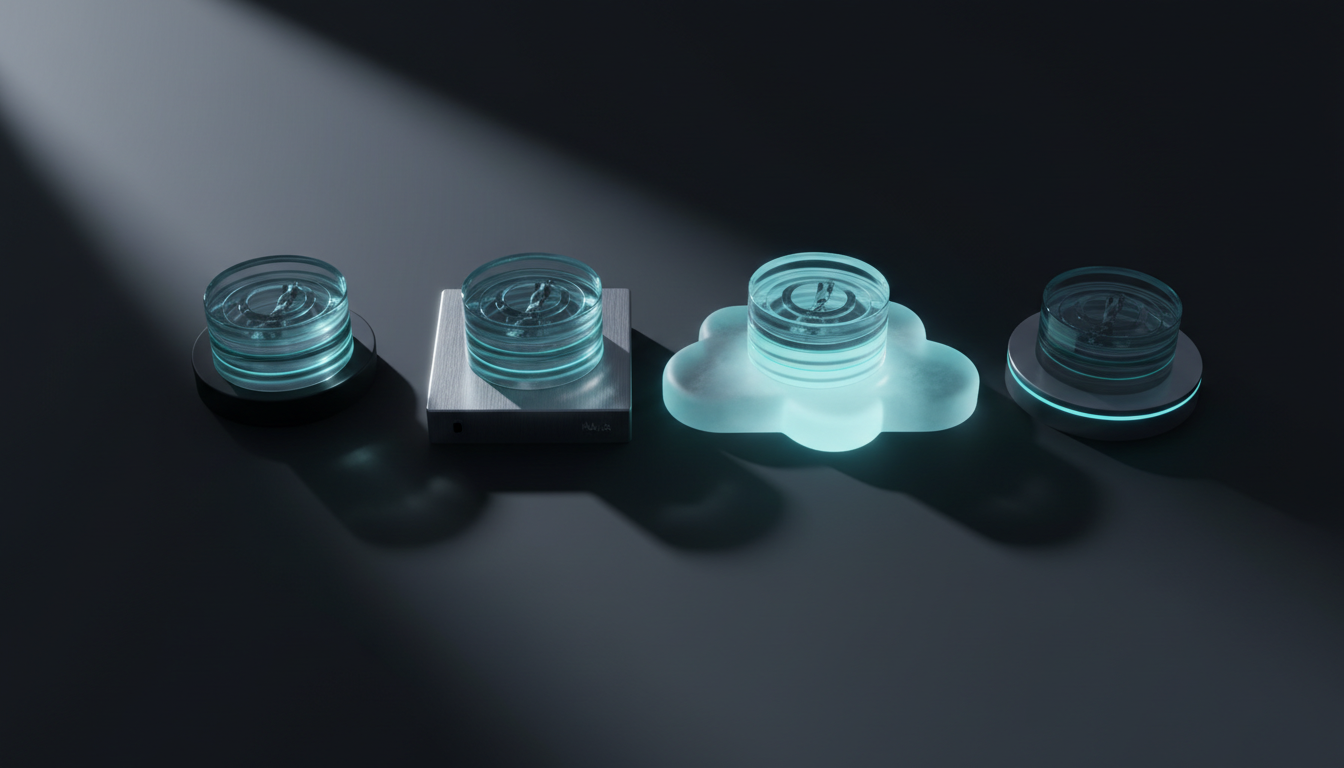
The logic is about eliminating single points of failure. A single storage type can fail for a single reason — a RAID controller dies, a ransomware strain targets a specific file system, a cloud provider has an outage. Diversifying media and location means no single event, technical failure, or attacker technique can take out every copy at once.
Why "2 different media" matters more than people think
If your production data lives on a SAN and your "backup" is a nightly copy to another volume on the same SAN, you have one copy of data in two locations, not two independent copies. The media type must genuinely differ: disk-based NAS, tape, cloud object storage (S3-compatible), or a dedicated backup appliance with its own authentication domain. Different media types usually also mean different failure modes and different attack surfaces — which is the entire point.
Why Ransomware Targets Backups First (And Makes the 3-2-1 Rule Non-Negotiable)
Modern ransomware operators follow a predictable playbook once they gain a foothold:
- Reconnaissance — identify backup software (Veeam, Commvault, etc.), backup servers, and storage repositories.
- Credential theft — target backup service accounts, which are often over-privileged domain admin or local admin accounts.
- Backup destruction — delete snapshots, disable repositories, or encrypt backup storage *before* encrypting production data.
- Encryption and extortion — encrypt production systems and threaten to leak exfiltrated data (double extortion).
CISA’s #StopRansomware Guide explicitly calls out backup destruction as a standard pre-encryption step in modern ransomware operations. If your backups are reachable from the same domain, with the same credentials, and on always-online storage, they are not a safety net — they’re just another target.
The 2021 Colonial Pipeline ransomware attack is a widely cited example of how a single point of failure — in that case, one compromised password — can cascade into a full operational shutdown. The same cascading-failure risk applies to backup infrastructure: if production and backup share credentials, a single compromise takes out both.
This is why the 3-2-1 rule’s off-site and media-diversity requirements aren’t theoretical hygiene. They are the difference between restoring from last night’s backup and negotiating with a criminal group.
Step-by-Step: Implementing the 3-2-1 Backup Rule for Ransomware Recovery
Step 1: Classify what actually needs protecting
Not all data deserves the same RPO/RTO. Start with a data inventory: identify systems that, if lost for 24–48 hours, would stop the business (ERP, email, domain controllers, customer databases) versus systems that can tolerate longer recovery windows. This classification works best alongside a broader internal vulnerability assessment that identifies which systems are exposed and most critical in the first place. This classification drives your backup frequency and cost allocation.
Step 2: Build Copy #1 — local, fast-recovery backup
Use a backup solution (Veeam, Commvault, Bacula, or an open-source option like restic or Borg) to take regular backups to local disk or a NAS appliance. This copy exists for speed — recovering a single deleted file or a corrupted VM shouldn’t require pulling data from the cloud.
- Daily full or incremental backups depending on change rate.
- Store on a separate storage system from production, not a partition on the same server.
Step 3: Build Copy #2 — a different medium
Replicate or independently back up to a second medium type:
- Cloud object storage (S3, Azure Blob, or an S3-compatible provider) using a dedicated backup tool connector.
- Tape, if your organization still uses LTO for long-term archival — still common in regulated industries for its inherent air-gap.
The key test: if the primary backup system is completely compromised, does Copy #2 survive independently? If it shares credentials, network path, or management plane with Copy #1, it fails the test.
Step 4: Send one copy off-site (the "1")
Off-site today usually means cloud storage in a different account, region, or provider than your production environment — not just a different building. This decision should be part of a broader business continuity planning effort, not an isolated IT choice made by whoever happens to be configuring the backup tool that week. For organizations in the GCC with data residency requirements, confirm the cloud region satisfies local regulations (e.g., UAE or Saudi data protection rules) before committing to a provider.
Step 5: Restrict access with separate credentials
Backup repositories should use dedicated service accounts that are not domain administrators and are not reused anywhere else. Enable multi-factor authentication on the backup console itself. If an attacker compromises your Active Directory, that compromise should not automatically extend to your backup infrastructure.
Step 6: Automate and monitor
Set alerts for failed backup jobs, unexpected deletions, and repository size anomalies (a sudden drop in backup size can indicate encryption or deletion in progress). A centralized log monitoring platform that ingests backup job logs alongside security events makes these anomalies far easier to catch in real time, rather than discovering them during an incident. A backup job that "succeeds" silently for six months while actually failing is a common root cause in real incidents.
Step 7: Test restores on a schedule
A backup you have never restored is a hypothesis, not a plan. Schedule quarterly restore tests for critical systems and document the actual time it took — this is your real RTO, not the number on a slide.
The Modern Upgrade: 3-2-1-1-0
Ransomware’s targeting of backup infrastructure has pushed the original rule to evolve. Many practitioners and vendors now recommend 3-2-1-1-0:
- 3 copies, 2 media types, 1 off-site — as before
- 1 copy that is immutable or air-gapped — cannot be altered or deleted even with valid credentials, for a defined retention window (object lock / WORM storage, offline tape, or a hardened Linux repository with immutability flags)
- 0 errors — verified, tested backups with zero unresolved failures
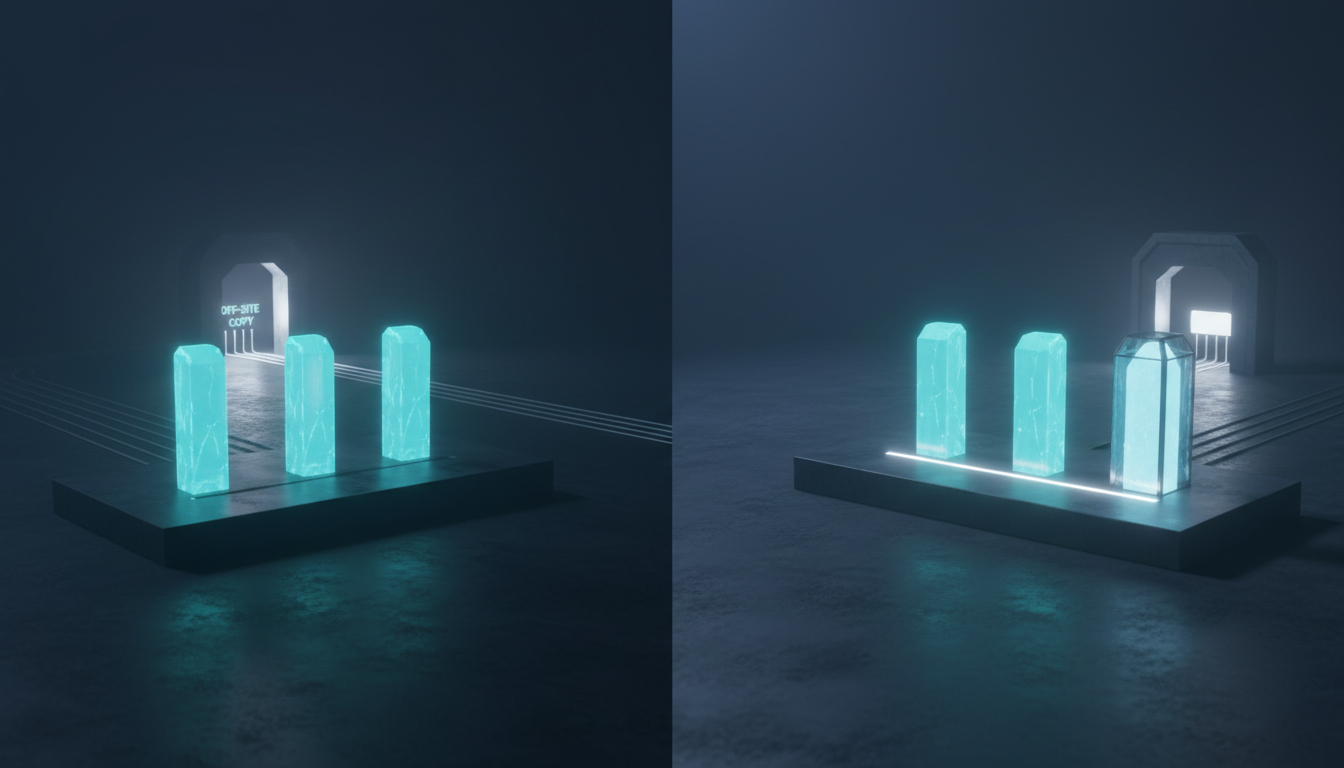
The immutable copy is the single most important addition for ransomware resilience specifically. Object lock features (available on AWS S3, Azure Blob immutable storage, and most S3-compatible platforms) let you set a retention period during which no user — including an account administrator — can delete or overwrite the data. This directly neutralizes the "attacker deletes backups before encrypting" step of the ransomware playbook.
Common Mistakes and Misconceptions in 3-2-1 Backup Strategy
"We have backups, so we’re covered." Having backups and having *recoverable, tested, isolated* backups are different claims. Many organizations discover their backups were encrypted alongside production data only during the actual incident.
Treating replication as backup. Database replication, RAID, and storage snapshots on the same array protect against hardware failure, not against ransomware or accidental deletion that replicates instantly to the mirror.
Using the same identity provider for backup access. If your backup console authenticates through the same Active Directory that got compromised, the attacker effectively has backup access too.
Never testing restores. A successful nightly job notification is not proof of recoverability. Corrupted backups, incomplete application-consistent snapshots, and missing dependencies (DNS, licensing servers, certificate authorities) are routinely discovered only during a real test — or worse, a real incident.
Ignoring recovery time in planning. Having 50 TB of backups in cold cloud storage with no tested retrieval plan can mean a multi-day restore when the business needs it back in hours. Factor retrieval speed into your storage tier choice, not just cost per gigabyte.
Forgetting configuration and identity systems. Teams often back up file servers and databases diligently but forget Active Directory, DNS, certificate authorities, firewall configs, and SaaS configurations — all of which are needed for a full recovery, not just data restoration.
FAQ: 3-2-1 Backup Rule and Ransomware Recovery
Is the 3-2-1 rule still relevant with cloud-native and SaaS environments?
Yes, but it needs adaptation. SaaS platforms like Microsoft 365 and Google Workspace are not automatically backed up by the vendor beyond short retention windows for recoverable items. You still need an independent backup copy of SaaS data, stored outside the platform’s own infrastructure, to satisfy the off-site and media-independence principles.
How often should backups run?
It depends on your Recovery Point Objective (RPO) — how much data loss is acceptable. Critical transactional systems often need near-continuous or hourly backups; less critical file shares may be fine with daily backups. Define RPO per system during the classification step, not as a blanket policy.
Does cloud storage count as the "off-site" copy automatically?
Only if it is genuinely isolated — a separate account, separate credentials, and ideally a different provider or region than your production environment. A cloud backup stored under the same tenant and admin credentials as your production Microsoft 365 environment does not provide real isolation.
What’s the difference between immutable backups and air-gapped backups?
Air-gapped means physically or logically disconnected from the network most of the time (offline tape, disconnected drives). Immutable means the data cannot be altered or deleted for a set period even while connected, enforced by the storage platform itself (object lock/WORM). Both defeat backup-deletion attacks; many mature strategies use both.
How long should we retain backups?
This should be driven by your recovery needs and any regulatory retention requirements applicable to your industry and jurisdiction, not just storage cost. Many ransomware incidents are discovered weeks after initial compromise, so retain enough historical versions to restore from a point before the intrusion began — commonly 30–90 days of versioned backups at minimum, longer for regulated data.
Free Resources
- CISA #StopRansomware Guide — Joint CISA/MS-ISAC guide covering ransomware prevention, response, and backup best practices.
- NIST SP 800-34 Rev. 1: Contingency Planning Guide for Federal Information Systems — Foundational framework for backup, recovery, and contingency planning.
- NIST SP 800-184: Guide for Cybersecurity Event Recovery — Structured approach to recovery planning after a cybersecurity incident.
- CIS Critical Security Controls — See Control 11 (Data Recovery) for a prioritized checklist of backup and recovery practices.
- restic — Free, open-source, encrypted backup tool supporting multiple storage backends, useful for building independent, media-diverse backup copies.
Conclusion: Make the 3-2-1 Backup Rule Your Ransomware Recovery Baseline
The 3-2-1 rule survives decades of technology change because it addresses a permanent problem: any single storage location, medium, or credential set can fail or be attacked. Ransomware has simply made the consequences of ignoring that problem far more severe and far more immediate.
Three takeaways to act on this week:
- Verify that your off-site/second-medium backup copy does not share credentials or network access with production.
- Confirm at least one backup copy is immutable or air-gapped, with a defined retention window attackers cannot override.
- Schedule an actual restore test for your most critical system in the next 30 days and record the real recovery time.
Treat this as part of your organization’s broader NIST Cybersecurity Framework 2.0 maturity uplift rather than a standalone IT project — backup resilience is one control among many, and it performs best when it’s tied to the same governance cadence as the rest of your security program.
A backup strategy is only as strong as its last successful, tested restore — not its last successful backup job.